From Mexico, I’ll be honest about how I use coding models: most of my day goes to big hosted assistants, and every so often I try a local model, get frustrated and go back. On October 21, Recursive released Flint, a free coding model built to run on a laptop, and the more interesting part is how it was made. Recursive says its own automated research system helped build almost all of it.
What Flint is
Flint is a mixture-of-experts model with 40 billion total parameters that activates just 2.5 billion per token, which is what makes it light enough for local hardware. Recursive says it’s built for fast agentic coding, and the Hugging Face model card says it’s designed to investigate codebases, fix bugs, implement features and write tests. The weights are on Hugging Face under the Apache 2.0 license, and Recursive lists support for llama.cpp, Ollama, Unsloth, LM Studio, vLLM and SGLang, plus its own lightweight inference engine, rec, for newer Apple chips.
The numbers are Recursive’s own, so read them that way. It says Flint leads mixture-of-experts models under 50 billion parameters on SWE-Bench Pro v2, Terminal-Bench 2.1 and SWE-Bench Verified, where the model card reports 74.2%. On speed, it claims more than 125 tokens per second on an M4 Pro MacBook Pro and more than 150 on a 64GB NVIDIA RTX Spark at short contexts. TechCrunch reports that in Recursive’s tests similar models managed 58 to 69 tokens per second on the same MacBook.
The AI that helped build it
Recursive calls its research system the Eureka Machine. It proposes ideas, implements them, tests them and uses the results to decide what to try next, exploring several directions in parallel. The company says a small team of people and agents built Flint from scratch in under four months, with the Eureka Machine contributing to data, training recipes, infrastructure and inference.
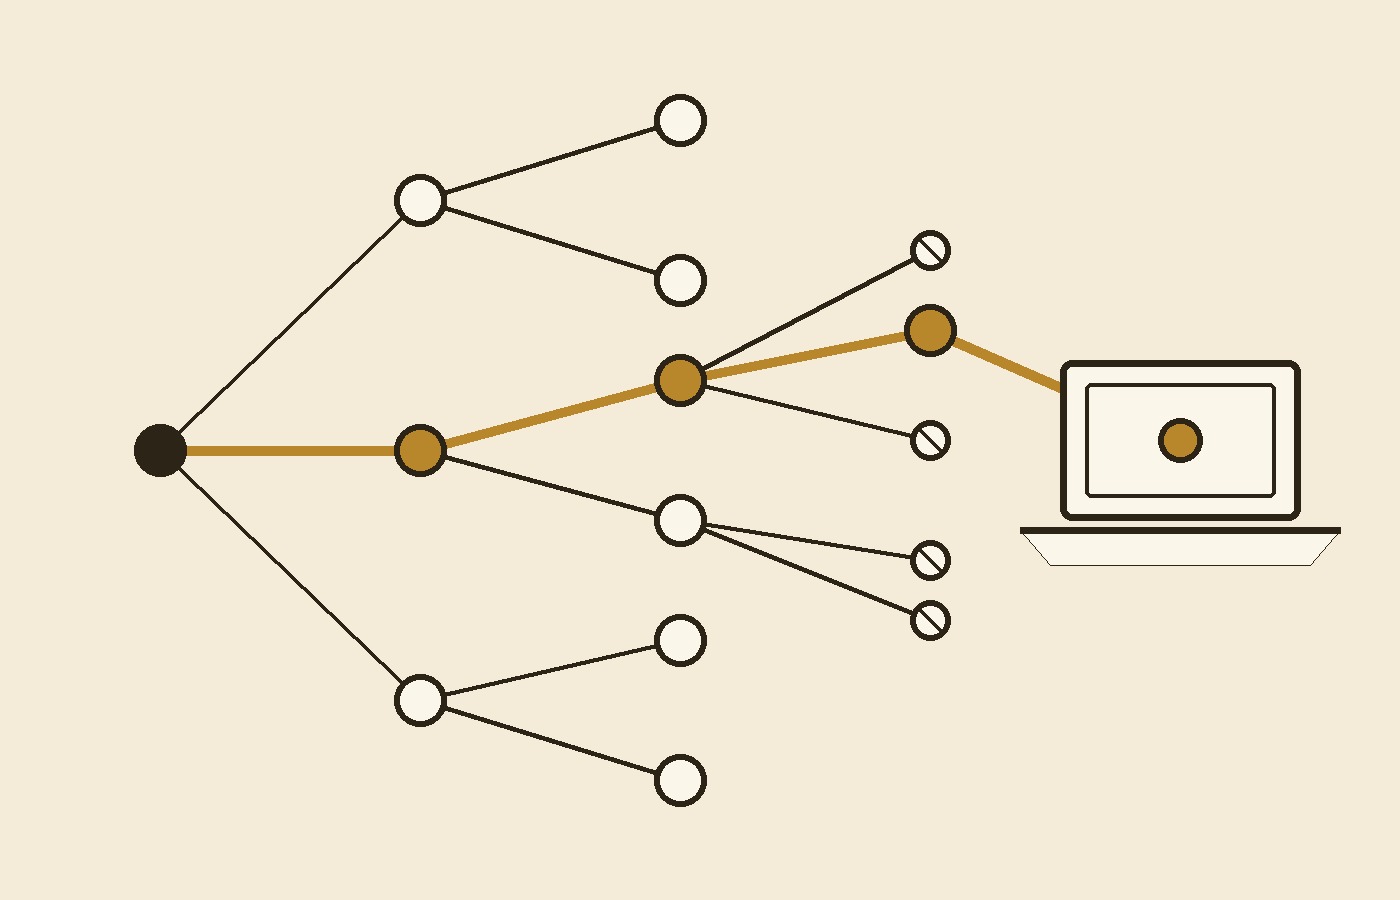
The examples are specific. It searched expert configurations starting from a 35 billion parameter baseline and landed on the 40B/2.5B shape. It quantized the output layer to 4 bits, against common practice, and added a distillation step to recover accuracy; Recursive says the final NVFP4 model scores within 0.7 points of the 16-bit one. It also wrote custom kernels, including a Metal megakernel for M4 and M5 chips. CEO Richard Socher told WIRED, “Nearly every aspect of the entire model pipeline was actually done and improved upon by AI.”
My take
Two things stand out to me. First, Recursive is upfront about the limits: it says Flint may need more guidance than the larger closed models you’re used to, and suggests breaking complex tasks into smaller subtasks with explicit instructions. It supports up to 512k tokens of context but recommends staying within 256k. That’s a useful, honest framing. A local model is a tool for private code, offline work and avoiding API fees, not a drop-in replacement for the biggest hosted assistants.
Second, the “AI built it” story matters more for how software teams work than it sounds. If an automated loop can search architectures, quantization recipes and kernels faster than a big team, the same pattern will show up in our own tooling: agents that try many variants and keep what actually measures better. I’d still want independent benchmarks before trusting the speed claims. But I’m going to try Flint on a small refactor this week, and I’d suggest you test it on your own repo before you believe anyone’s leaderboard, including Recursive’s.
Featured image: “Knapped Flint Nodule” by Colin Smith, Wikimedia Commons (geograph.org.uk), CC BY-SA 2.0. Cropped, resized to 1400×900 and lightly sharpened; the modified image is shared under the same license.